20 October 2026 · dated development task-log handoff
New preparation is ready for review. The next tests have not passed.
Seven provided screenshots record follow-up work after the independent tests in Reports 68–70. They show an Evelyn eyelid-calibration correction being prepared and source-reviewed, plus NewBrain preflight and source-closure interruptions. These are development-status observations, not newly successful model or motion tests.
1.68% / 1.74%
Measured closure in the previously failed test; requirement was 65% on both lids. Later code review is not a passing retest.
Original12: 2/12
The screenshoted diagnostic preparations stopped before a new model result. Qwen comparison remains untested.
2/3 → 3/3 → 3/3
Three explicitly rehearsed synthetic answers retained after a distinct restart (Report 68). Not the Original12 benchmark.
Evelyn Hart: what changed and what remains blocked
The earlier owned-browser compatibility render accepted three distinct static head views. Separately, the first motion study failed the predetermined blink gate: eyelid aperture reduction was 1.68175% left and 1.74329% right, below 65%. Jaw calibration passed, but the six combined motion captures and optional video were not produced.
The follow-up task screenshots identify a small 0.5° scouting movement in the calibration as a limitation. They report a code correction that searches for sufficient eyelid travel, while preserving eye-stability and return-to-rest checks. The correction was reported as passing independent source review; that is code review, not a passing animation test.
The next fresh trial was reported not to have started because available memory was below the existing 8 GiB startup guard. A bounded working-set correction was being applied without closing ChatGPT or saved processes; after the first correction, available RAM was still below the guard. The task was moving small coordination steps into a lighter process. The screenshots do not show a successful fresh blink or speech test following this work.
The controlled engineering audio waveform and neutral-frame checks are timing/software tests, not Evelyn speaking. Generated dialogue, verified audio output, synchronized lips, persistent visitor memories and public installation all remain unverified.
Actual accepted static head screenshots (previously published)
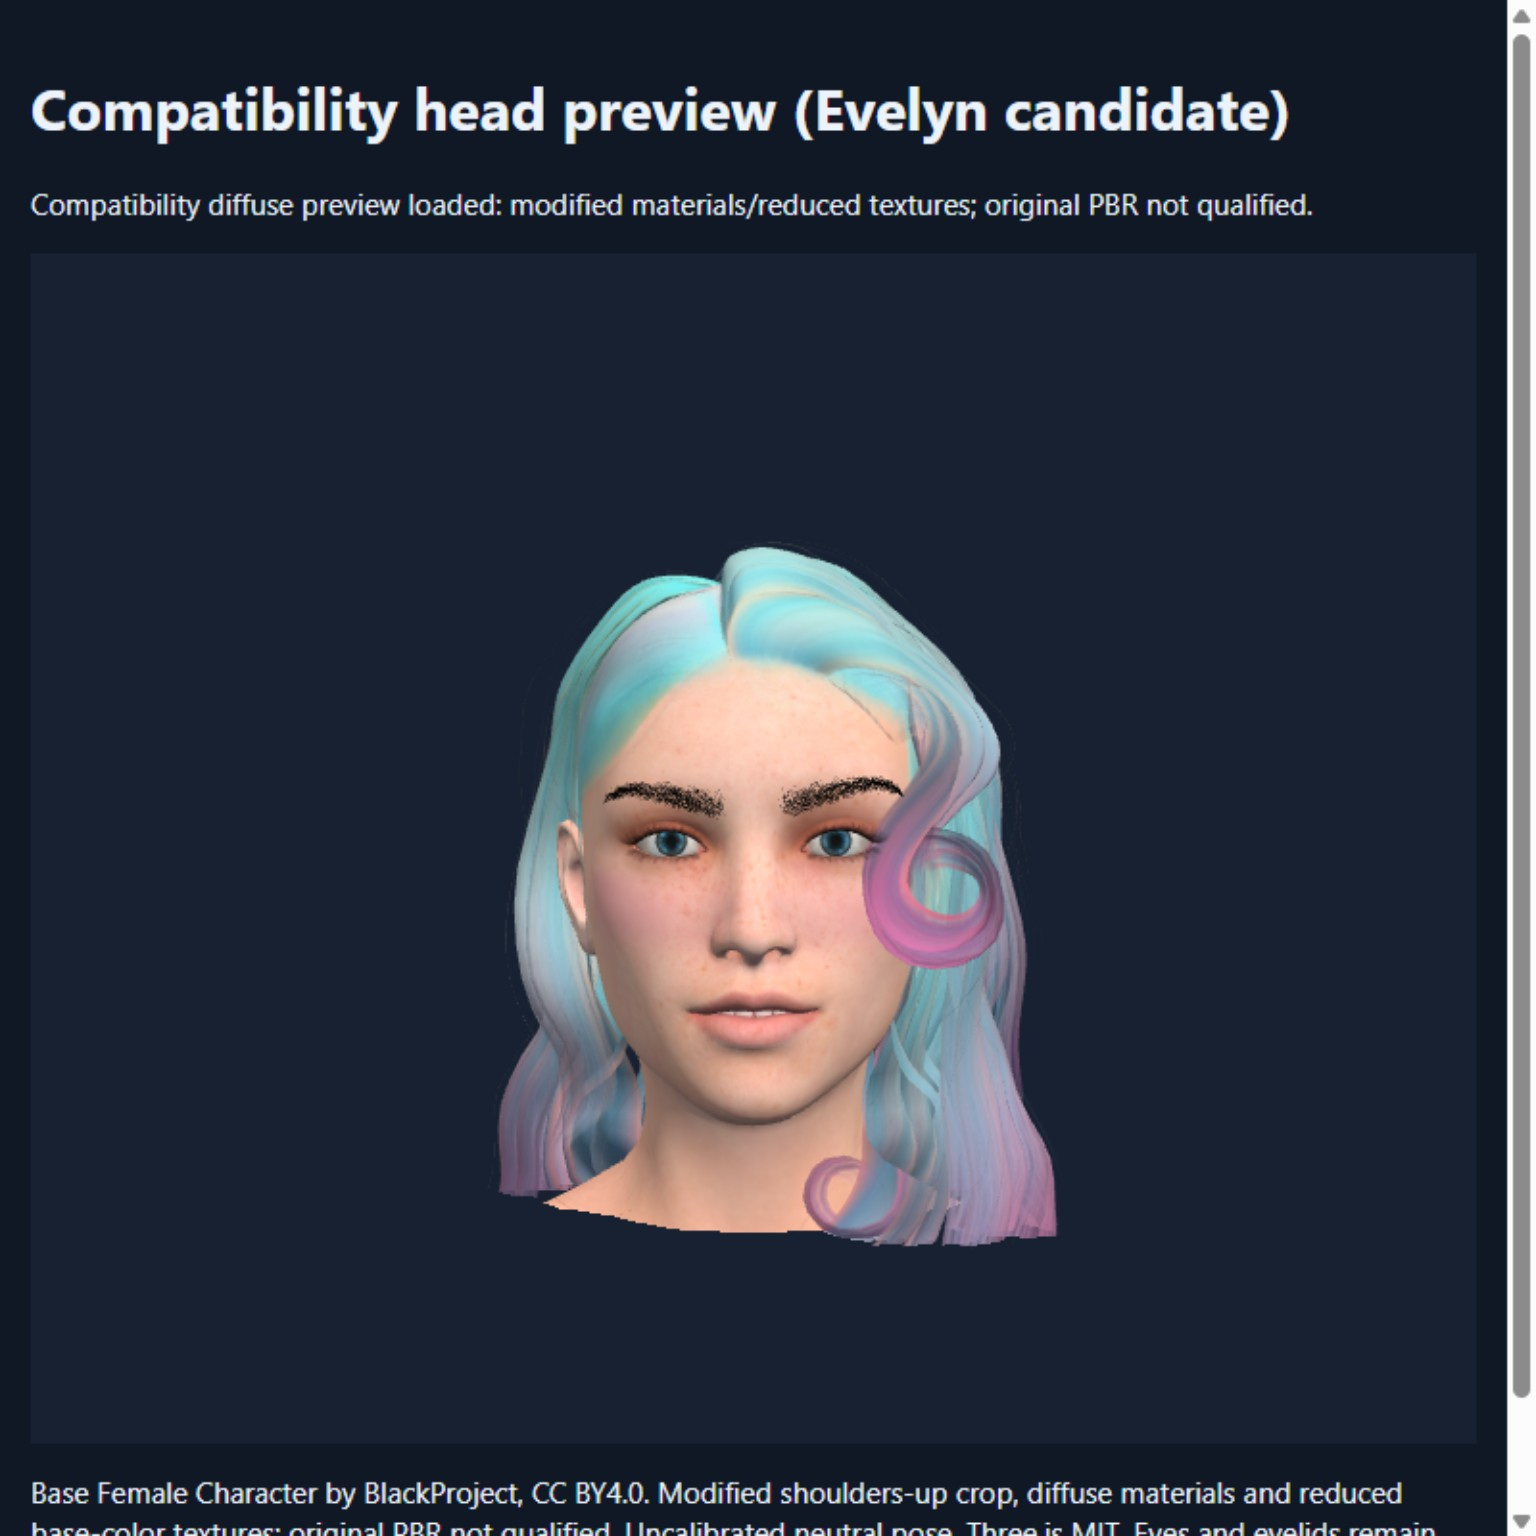
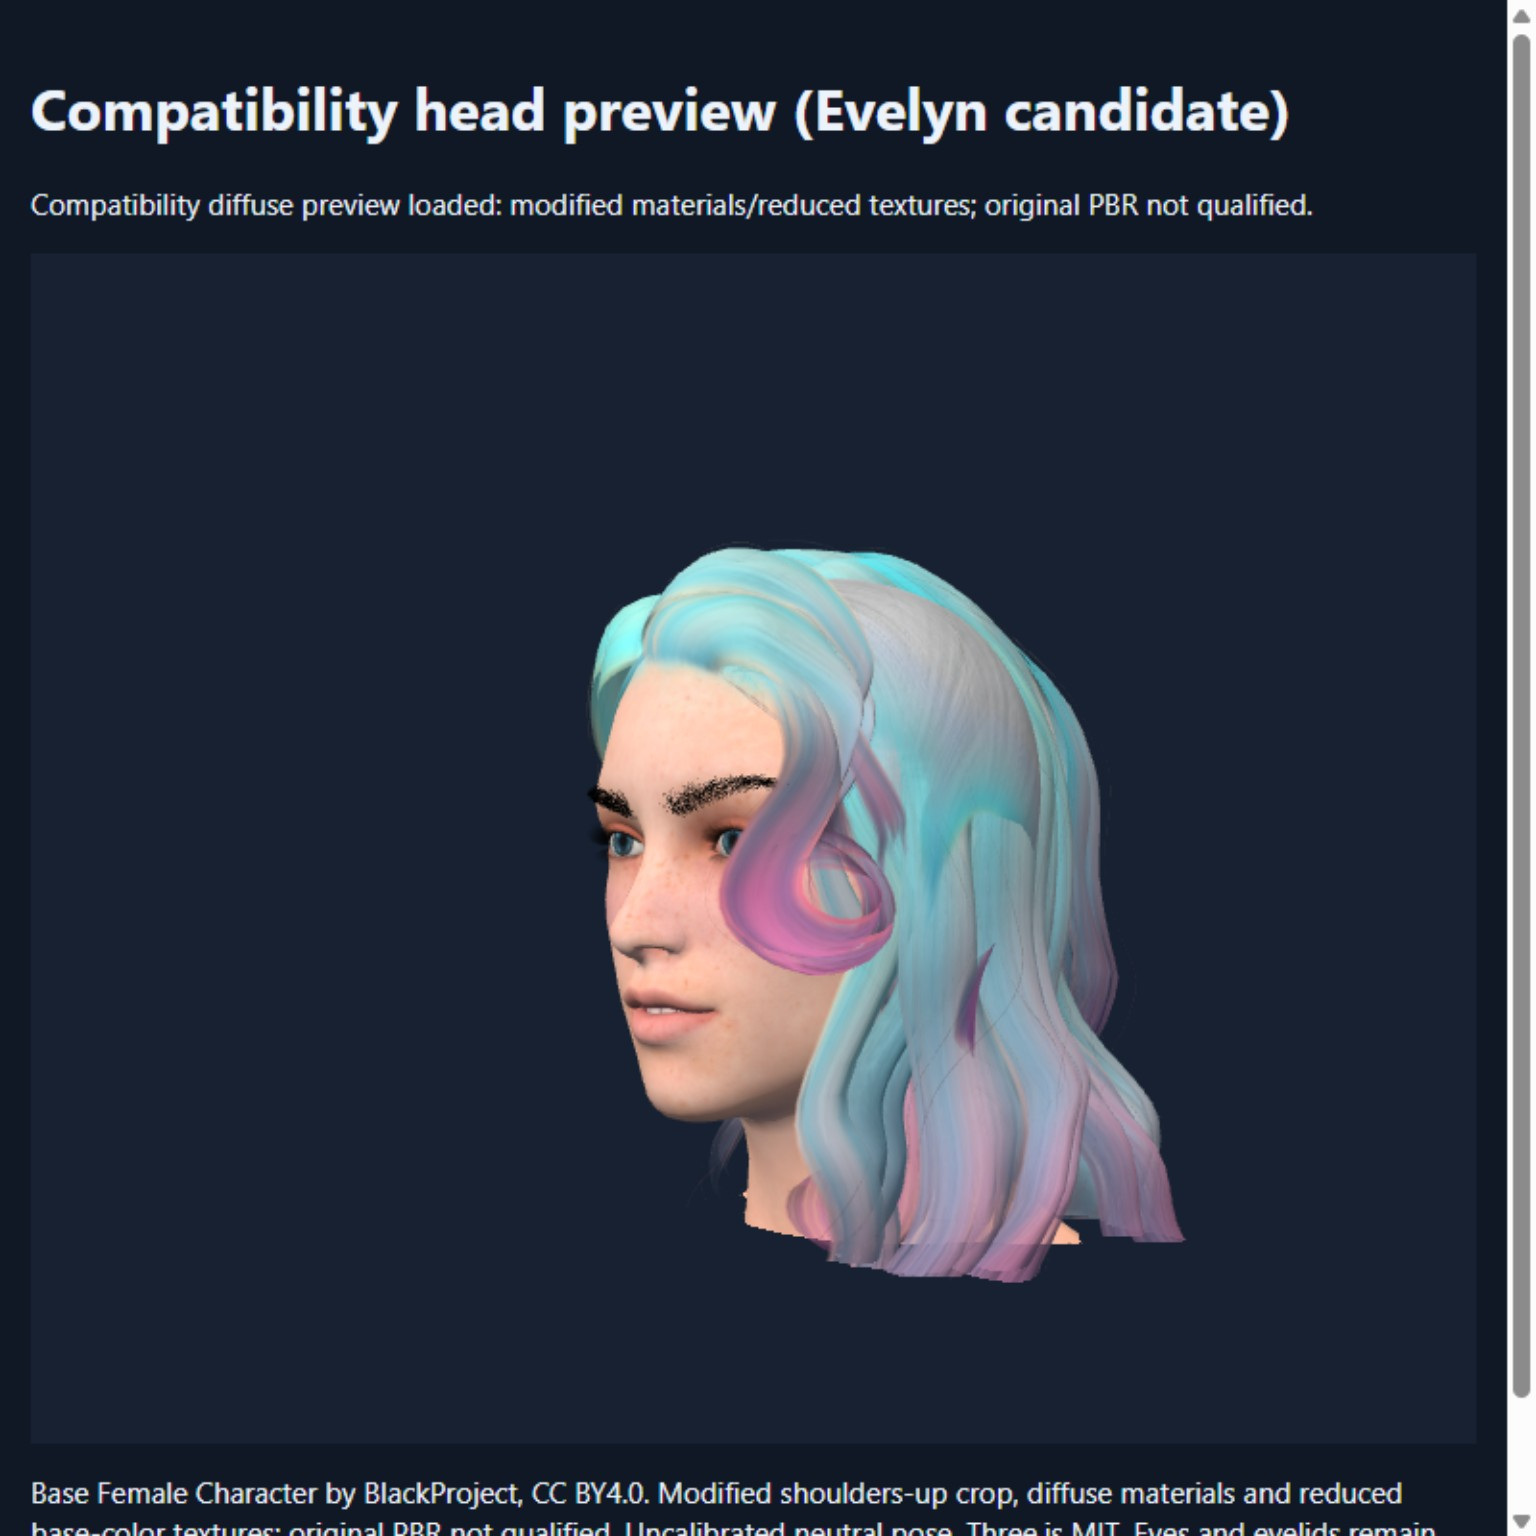
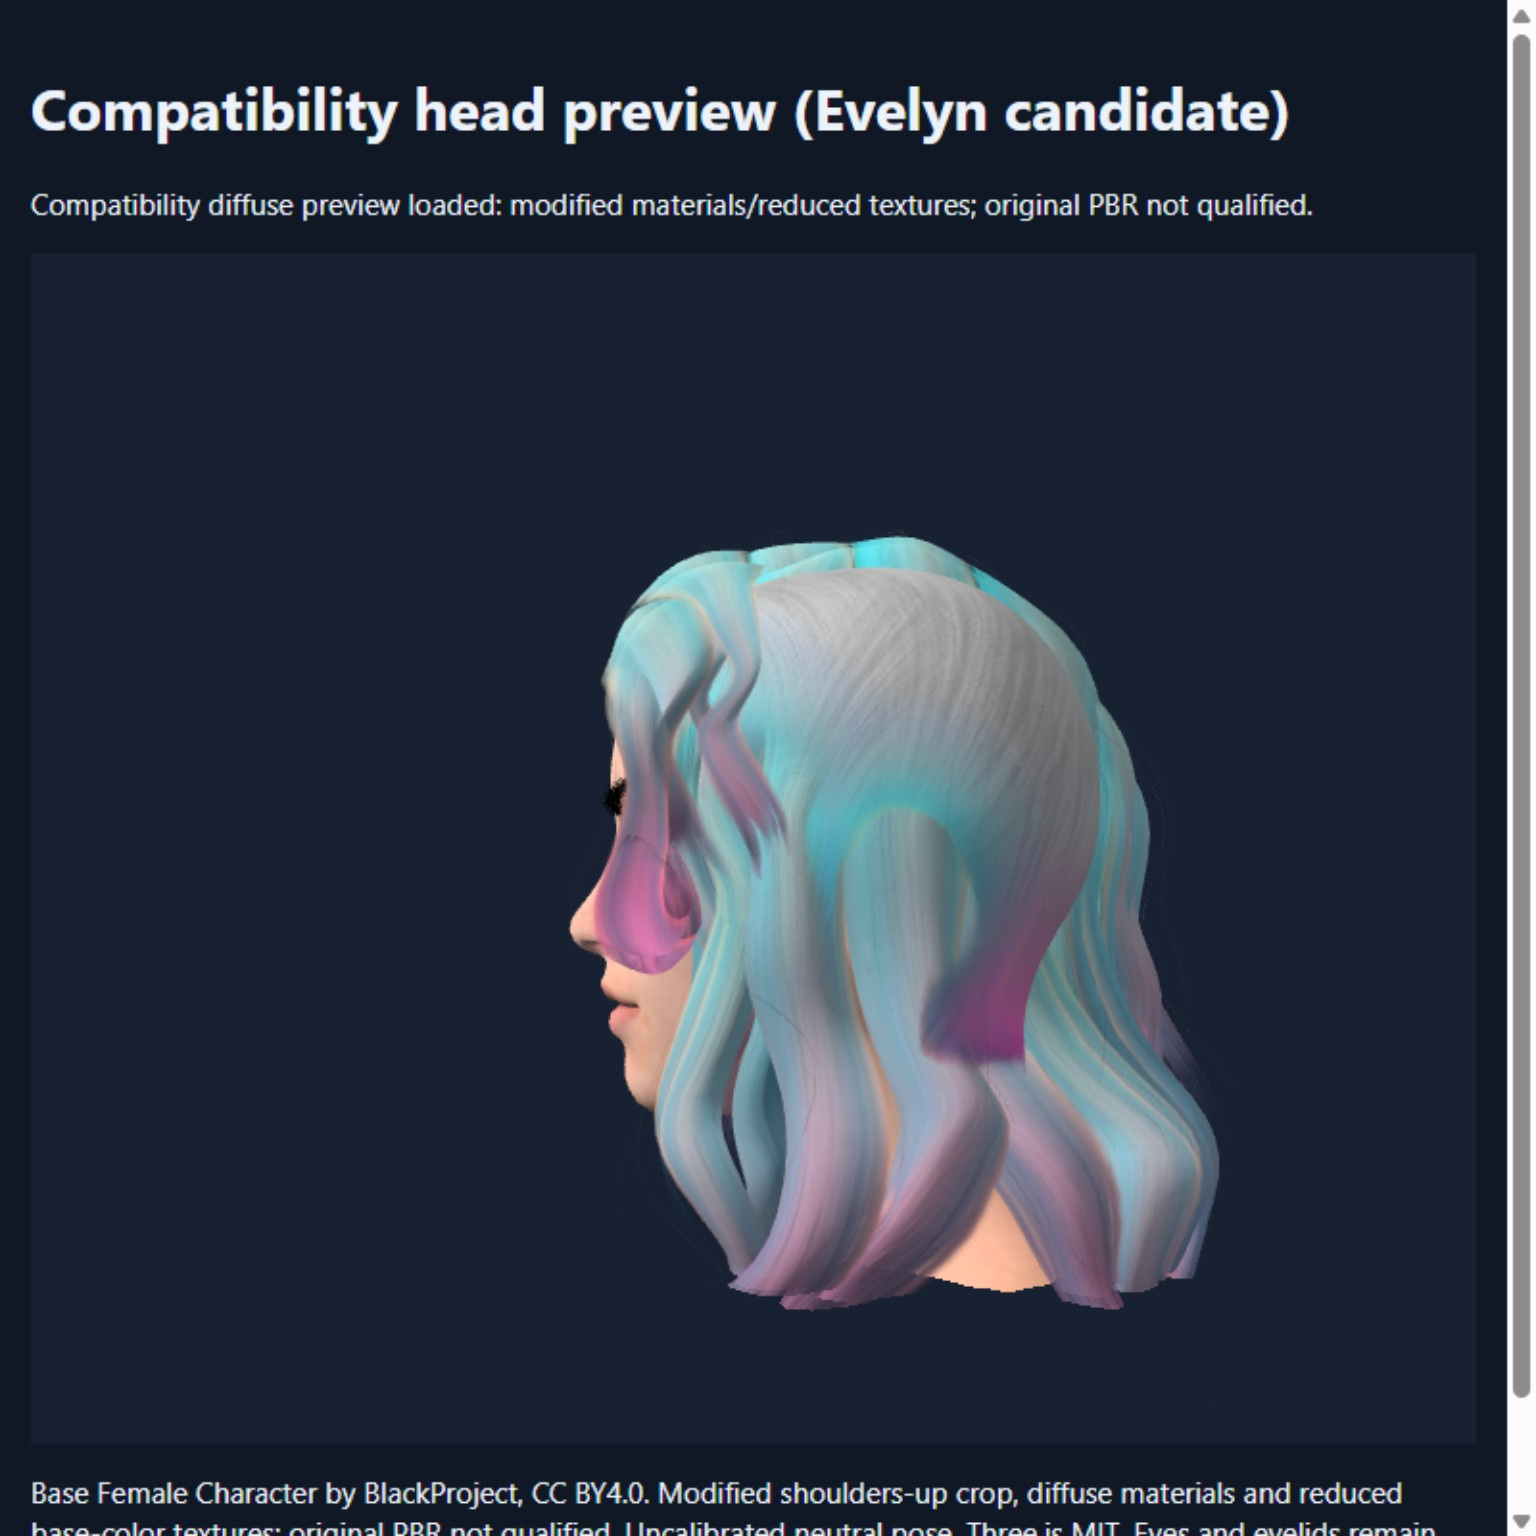
Read Report 70: head images and method → · Read the preserved motion failure →
NewBrain: a preparation block, not a new learning failure or gain
The supplied task screenshots show a planned fresh diagnostic that did not reach a model measurement. Available RAM failed the unchanged 8 GiB startup check on one attempt. In another preparation, the source-closure record supplied the wrong field name; the constructor stopped before a model/Native call. Failed preparations were kept, with cleanup and independent review reported as closed.
The development messages describe a corrected source-closure call passing independent code review and a bounded memory adjustment under way. Neither changed the accepted learning results, and neither establishes that the subsequent intended test actually ran.
| Assessment | Last accepted observation |
|---|---|
| Main Original12 | 2/12 before and 2/12 after the 256-update study and reload; no net gain |
| Rehearsed short three-row diagnostic | 2/3 → 3/3 → 3/3 following a distinct restart (Report 68) |
| Separate longer-answer diagnostic | 2/3 → 2/3; correct initial answer token but early end marker (Report 69) |
| Qwen model comparison | Unrun |
| Fresh diagnostic in the supplied screenshots | No model result; startup RAM and source-closure preparation blocks reported |
Report 68: positive short-answer restart → · Report 69: incomplete longer answer → · NewBrain project →
All research report reading editions → · Dated development updates →